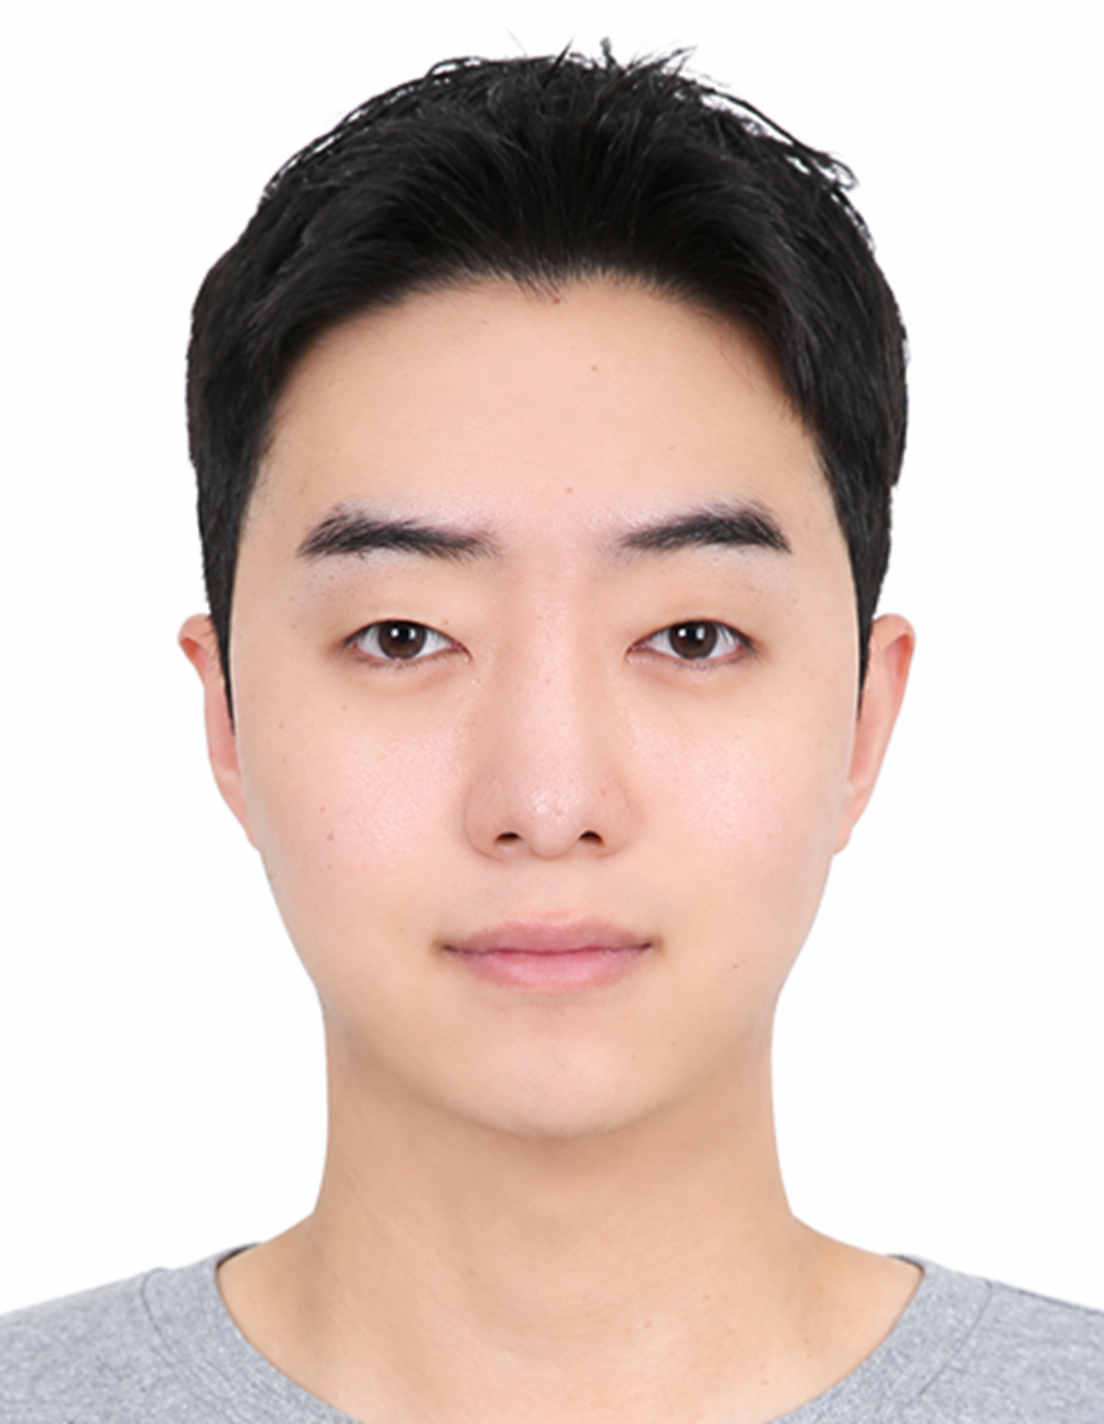
Beomjin Seo
AI Engineer · Seoul, South Korea
I'm currently an LLM/VLM engineer at Samsung Research, where I develop on-device AI models for Samsung smartphones used by millions of people worldwide. My work focuses primarily on the pre/post-training of VLMs, with an emphasis on hardware-friendly & efficient architectures and post-training methods.
Please feel free to reach out, whether you'd like to talk about research or just have a casual chat!
Personally, I hold the following perspectives:
- LM understanding
- LMs are essentially memory banks, and pre-training methods are different ways of injecting inductive biases into that memory
e.g., Transformers, Mamba, MoE, recurrent-depth, and so on. - Retrieval strategy matters too: autoregressive and diffusion-based methods are different ways to retrieve information, and post-training methods are different ways to retrieve the knowledge already encoded in the model.
- LMs are essentially memory banks, and pre-training methods are different ways of injecting inductive biases into that memory
- LM expansion for application tasks
- Exposure to diverse environments during training is key - not just non-physical data (e.g., the internet), but physical environments as well.
- Unfamiliar distribution shifts make modality expansion challenging - models often struggle to decide whether to rely on the language prior.